Category: Uncategorized

How ETL Became a Four-Letter Word and What Replaced It

The Pipeline Nobody Wanted to Admit Was Broken

There was a time when mentioning ETL in a job posting signaled seriousness. You had data, you had a warehouse, and you had a process for moving the first into the second. That process was ETL: Extract, Transform, Load. It sounded clean. It sounded like engineering. And for a while, it worked well enough that nobody questioned it.

Server racks in a data center representing traditional ETL infrastructure

Then somewhere around 2015, the complaints started stacking up. ETL pipelines were brittle. They broke when source schemas changed. They required specialized developers who wrote proprietary transformation scripts nobody else could read. The transformation layer became a bottleneck—data sat in staging tables waiting for someone to fix a truncation error in a column nobody remembered mapping. ETL didn’t scale with data volume, and it didn’t scale with organizational complexity. But the real problem was simpler: ETL assumed you knew what you needed before you looked at the data.

What Went Wrong

The original sin of ETL wasn’t the technology. It was the assumption. Traditional ETL assumed a clean separation between extraction and transformation, where business rules could be defined upfront and applied consistently. In practice, this meant a small team of ETL developers became gatekeepers. Want a new field in the report? File a ticket. Wait three weeks. Discover the field was calculated wrong? File another ticket.

The problems fell into a few recognizable categories:

  • Brittle schema dependencies: A source system adds a column, and three pipelines break overnight. Fixing them requires touching scripts that haven’t been updated since someone named Dave wrote them in 2017.
  • Opaque transformation logic: Business rules buried in Informatica workflows or SSIS packages that no one can audit without opening a proprietary GUI.
  • Slow iteration cycles: Every new data source requires a full ETL design, development, and testing phase before anyone sees a single row.
  • Orphaned pipelines: When the person who built the pipeline leaves, the pipeline becomes archaeological evidence rather than maintained infrastructure.

None of this was inevitable. Some organizations ran ETL well for years. But the pattern repeated often enough that when alternatives appeared, the market was ready to declare the entire category obsolete.

Enter ELT

A person working on data systems at a computer representing modern data engineering

The replacement arrived with a letter rearrangement: ELT. Extract, Load, Transform. The logic was straightforward—move raw data into the warehouse first, then apply transformations using the warehouse’s compute power. Snowflake and BigQuery could handle transformations at scale. Why maintain a separate transformation engine when the warehouse has more compute than you’ll ever need?

dbt made this approach mainstream. Write SQL, version control it, test it, document it. Transformation became software engineering, or at least something adjacent to it. The benefits were real:

  • Raw data availability: Analysts can inspect source data before transformation, catching issues early.
  • Version-controlled logic: Transformations live in Git, not in a proprietary repository with export limitations.
  • Faster iteration: Want a new metric? Write a SELECT statement. Deploy it. Done.
  • Transparent calculations: Anyone with SQL access can read the transformation logic.

This was a genuine improvement. But the marketing around ELT sometimes implied that moving the letter “T” solved everything. It didn’t. ELT moved the complexity; it didn’t eliminate it.

The Problems ELT Inherited

Here’s what the ELT proponents don’t always mention: loading raw data first means your warehouse becomes a dumping ground if nobody gets around to the transformation layer. The number of organizations with massive Snowflake bills and a raw schema nobody has touched in months is not small. ELT解决了 the visibility problem but introduced a cost problem. Compute is cheap until it isn’t.

The transformation layer also became fragmented. Instead of one Informatica workflow, you now have forty dbt models maintained by different teams with different testing standards. Centralization shifted to fragmentation. Whether that’s better depends on your governance structure and whether anyone enforces it.

And the original brittleness problem? Still there. Source schema changes still break things. The difference is that now the breakage manifests as a dbt test failure at 2 AM instead of an SSIS error at 6 AM. You’ve changed the timing and the tool, but the fundamental dependency on upstream schema stability remains.

What Actually Replaced ETL

The honest answer is that nothing single replaced ETL. Instead, the concept fragmented into several approaches, each addressing a different aspect of the original problem. If you’re building data infrastructure today, you’re likely combining multiple patterns rather than adopting one replacement.

Change Data Capture (CDC)

CDC tools like Debezium track changes at the source database level and propagate them downstream. Instead of running a nightly batch extract that pulls everything, CDC streams only what changed. This solves the latency problem—data arrives in minutes rather than hours. It also reduces load on source systems, which your database administrators will appreciate.

CDC isn’t without trade-offs. It requires operational discipline at the source. Transaction logs must be available and retained long enough for the capture process to read them. If your source system is a SaaS product you don’t control, CDC may not be an option at all.

Streaming Pipelines
Network cables and switches representing data pipeline infrastructure

Kafka and similar platforms enabled a different model entirely—continuous data flow rather than batch extraction. Streaming makes sense when freshness matters. Fraud detection, real-time inventory, operational dashboards—these use cases need data within seconds, not hours.

The cost of streaming infrastructure is significant, and most organizations don’t need it for most of their data. A daily batch load handles 80% of analytical workloads perfectly well. The remaining 20% may justify streaming, but only if you can articulate which 20% and why. Building a Kafka cluster because it sounds modern is how you end up with expensive infrastructure nobody monitors properly.

Data Contracts and API-First Approaches

A quieter but potentially more significant shift is the adoption of data contracts—the idea that data producers and consumers agree on schema, freshness, and quality expectations before data moves anywhere. This directly addresses ETL’s brittleness problem. When the source system commits to a contract, downstream pipelines have a stable foundation.

This approach requires organizational maturity and willingness to negotiate. It also works better for internal data sources than external ones. You can’t negotiate a data contract with a vendor API that changes without notice. But for internal systems, contracts enforce the discipline that ETL always assumed but rarely got.

Reverse ETL

Once data lands in the warehouse and gets transformed, someone usually needs it pushed back out to an operational system—CRM, marketing platform, support tool. Reverse ETL tools handle this, closing the loop. It’s a practical recognition that data doesn’t just flow in one direction toward a dashboard. It flows back out to where operational decisions happen.

What Matters More Than the Acronym

The ETL-versus-ELT debate was never the right argument. The real question is simpler: can you trace a number from its source to its destination, explain how it was calculated, and fix it when it breaks?

If the answer is no, your architecture is the problem, not your acronym. I’ve seen ETL systems that were well-documented, tested, and maintained. I’ve seen ELT systems that were an unmaintainable mess. The pattern matters less than the execution.

A few practical principles that survive any architectural trend:

  • Know your lineage: If you can’t trace a metric back to its source, you don’t have a pipeline—you have a mystery.
  • Test what matters: Not every column needs a uniqueness test. But every financial calculation needs a reasonableness check.
  • Document decisions: Why was this transformation written this way? If the answer is “that’s how Dave did it,” you have a documentation problem.
  • Monitor actual usage: If nobody queries a table, stop maintaining the pipeline that feeds it. Unused data infrastructure is debt.
  • Own your dependencies: Every external system you depend on will change. Plan for it.

The current generation of data tools is better than what came before. But tools don’t substitute for thinking. ETL became a four-letter word not because the pattern was inherently flawed, but because organizations deployed it without discipline and then blamed the acronym when things fell apart. The replacements carry the same risk.

FAQ

Is ETL completely dead?

No. Batch ETL still handles the majority of analytical data workloads in most organizations. The nightly load into the warehouse remains common because most reporting doesn’t require real-time data. What’s changed is that ETL is no longer the only pattern available, and new projects often default to ELT instead. But declaring ETL dead is more about marketing than engineering reality.

Should every organization move to streaming?

Absolutely not. Streaming infrastructure is expensive to build, expensive to maintain, and requires specialized skills most teams don’t have. If your dashboards update once a day and nobody complains, streaming is overkill. Adopt streaming when you have a specific, measurable need for data freshness measured in seconds or minutes—not because a vendor deck says it’s the future.

What’s the biggest risk in replacing ETL with ELT?

Warehouse cost and data governance. Loading raw data first means your storage and compute costs scale with data volume, not with actual usage. And without clear ownership of the transformation layer, the warehouse becomes a swamp of undocumented, untested models. ELT shifts responsibility rather than removing it. If your organization doesn’t have the discipline to maintain transformation logic, moving that logic to SQL doesn’t fix the underlying problem.
Why Your Data Pipeline Will Break at 3 AM and How to Prepare for It

It always happens at 3 AM. Not at 2 PM on a Tuesday when you’re sitting at your desk with coffee and a debugger. No, pipelines break when the on-call engineer is asleep, the senior architect is on vacation, and the Slack channel is silent. This is not coincidence. It is the natural consequence of how distributed systems degrade under load, under edge cases, and under neglect.

Server room with blinking status lights

The Anatomy of a 3 AM Failure

Pipelines don’t break at 3 AM because the universe is cruel. They break at 3 AM because that’s when the accumulated technical debt of the last six months finally tips over into failure. The timeout that was set too aggressively. The disk that’s been filling at 2% per week. The upstream API that silently changed its pagination behavior. None of these things trigger alerts at 10 AM. They wait until the conditions align—until a batch run coincides with a memory leak coincides with a network partition.

I’ve seen teams build elaborate architectures on top of foundations that can’t survive a single process restart. They’ll adopt event-driven microservices with schema registries and service meshes, but nobody bothered to set a retention policy on the message queue. The queue fills up, the consumer falls behind, and suddenly your real-time pipeline is hours behind at 3 AM on a Saturday.

The Usual Suspects

Here’s what typically goes wrong:

Resource exhaustion. Disks fill up. Memory gets consumed. Connection pools max out. These are boring, predictable failures that still catch teams off guard because nobody set up monitoring on something as unglamorous as disk usage trends.

Upstream changes. A vendor modifies their API response format. A source system upgrades and starts producing slightly different JSON. Your pipeline expects one schema and receives another, and the error handling consists of a single try-catch that logs the exception and moves on—silently dropping data.

Dependency failures. Your pipeline depends on a database, a message queue, and an object store. Each has its own failure modes. When the database starts rejecting connections because its connection limit is reached, your pipeline doesn’t gracefully degrade. It falls over.

Network cables in a data center

What Doesn’t Work

Before talking about what to do, let’s cover what doesn’t work. I’ve watched teams try all of these:

Throwing hardware at the problem. Scaling up the cluster feels productive. It’s also expensive and often masks the actual issue—a query that scans an entire table instead of using an index, or a transform that loads everything into memory instead of streaming.

Adding more layers of abstraction. Wrapping your pipeline in an orchestration framework doesn’t make it more reliable. It makes it harder to debug. When something fails at 3 AM, you don’t want to trace through three layers of framework code to find the actual error.

Assuming someone else is handling it. The cloud provider’s SLA covers their infrastructure. It does not cover your misconfigured security group, your application-level bug, or the data quality issue that’s been festering for weeks. Evolutionary architecture doesn’t mean ignoring operational fundamentals.

What Actually Works

1. Know Your Failure Modes

Document every dependency in your pipeline. For each one, ask: what happens when this fails? What happens when it’s slow? What happens when it returns unexpected data?

If the answer to any of these questions is “the pipeline crashes and requires manual intervention,” you have work to do. Your pipeline should degrade gracefully, not catastrophically. A downstream system being unavailable shouldn’t corrupt your data—it should pause processing and retry.

2. Set Meaningful Alerts

An alert that fires at 3 AM should mean something. Not “CPU is at 80%,” but “the ingestion lag has exceeded the two-hour threshold.” Alert on business impact, not on system metrics. If you’re waking someone up, that person needs to know what’s actually wrong, not just that some number crossed a line.

Set up alerts for:

  • Processing lag exceeding defined thresholds
  • Data freshness dropping below SLA requirements
  • Error rates spiking above baseline
  • Retry queues growing beyond expected bounds

3. Build Idempotency Into Everything

If your pipeline can’t safely reprocess data, it can’t recover from failures. Idempotency means you can run the same transform twice and get the same result. It means your writes use upserts instead of blind inserts. It means your pipeline can be restarted without producing duplicate records.

Without idempotency, every failure requires manual intervention to figure out where processing stopped, what data was partially written, and how to clean it up before restarting. At 3 AM, under pressure, that manual process is error-prone and slow.

Person working on laptop in dim lighting

4. Test Failure Scenarios

Chaos engineering gets treated as a trend, but the core idea is sound: deliberately break things in controlled conditions to verify they fail as expected. Kill a database connection mid-process. Fill up a disk partition. Return malformed data from a mock API. Watch what happens.

If you’ve never tested what happens when your primary database becomes unavailable at 3 AM, you’re gambling that the first time it happens, the pipeline will behave correctly. That’s a bad bet.

5. Write Runbooks, Not Just Code

Every known failure mode should have a runbook. Not a wiki page that was last updated eight months ago—a tested, version-controlled document that the on-call engineer can follow at 3 AM without thinking creatively.

A good runbook includes:

  • What the alert means in plain language
  • Steps to confirm the diagnosis
  • Remediation steps, including rollback procedures
  • Escalation criteria and contacts

6. Implement Circuit Breakers

When an upstream system starts returning errors, stop hammering it. Implement circuit breakers that detect repeated failures and pause processing until the upstream recovers. This prevents cascading failures and reduces the blast radius of a single dependency going down.

A circuit breaker isn’t complicated. It’s a pattern: track failures, and after a threshold is reached, stop making calls for a cooldown period. Then test whether the downstream system has recovered before resuming normal traffic. It’s the kind of basic engineering practice that gets skipped when teams are focused on feature velocity.

The Boring Fundamentals Matter Most

None of what I’ve described is exciting. Circuit breakers, runbooks, idempotent writes—these aren’t the topics that get presented at conferences. They’re the operational basics that make the difference between a 3 AM page that takes 20 minutes to resolve and one that turns into a four-hour incident.

The teams that sleep through the night aren’t the ones with the most sophisticated architectures. They’re the ones who handled the fundamentals: they set up proper monitoring, they wrote runbooks, they tested their failure scenarios, and they built pipelines that can recover without manual intervention.

Your pipeline will break at 3 AM. The question isn’t whether it will happen—it’s whether you’ll be prepared when it does.

FAQ

What’s the first thing I should do to improve pipeline reliability?

Map your dependencies and failure modes. Before you can fix anything, you need to know where your pipeline is fragile. Document every external system your pipeline depends on, and for each one, describe what happens when it fails. Most teams find gaps in their understanding within the first hour of doing this exercise.

How do I convince leadership to invest in reliability work?

Quantify the cost of downtime. Track the time engineers spend on incident response. Calculate the business impact of data being delayed or incorrect. When leadership sees that a single 3 AM incident costs more in engineer time than a week of reliability work, the investment case becomes clear. Don’t frame it as technical debt—frame it as operational risk with a measurable cost.

Should I use an orchestration tool or build my own pipeline framework?

Use an existing tool. The operational complexity of running a pipeline is already high enough without maintaining custom scheduling, retry logic, and monitoring infrastructure. Tools like Airflow or Prefect handle these concerns so you can focus on your actual data transformations, not on rebuilding task scheduling. The exception is if you have requirements that genuinely can’t be met by existing tools—and that’s rarer than most teams assume.

Claude 3.7 Sonnet’s Extended Thinking Mode: The Production Reality Behind the Benchmark Headlines

The Extended Thinking Bet: What Actually Changed in February 2025

When Anthropic dropped Claude 3.7 Sonnet in February 2025, the headline feature wasn’t another marginal capability bump. It was extended thinking mode, a fundamentally different approach to how the model tackles complex reasoning problems. Before you output your answer, the model gets to think. Actually think. For up to 128K tokens if you configure it that way. It’s the kind of architectural choice that makes you sit back and recognize someone understood the actual problem.

The premise is straightforward enough: give the model space to reason through multi-step problems internally before committing to a response. No more immediate output pressure. No more trading depth for latency. Just reasoning tokens that never reach the user but fundamentally change what the model can attempt. From a systems perspective, it’s elegant. From a production perspective, it’s a minefield of tradeoffs you need to understand before deployment.

What’s genuinely interesting is that this isn’t speculative architecture anymore. This is shipping technology with real constraints and real costs. The Anthropic Claude 3.7 Sonnet release announcement laid out the capabilities, but the production implications are where the real story lives.

The Benchmark Signal: Where Extended Thinking Actually Proves Its Value

Let’s start with what the numbers actually tell us, because this is where extended thinking earns credibility beyond the marketing narrative. On SWE-bench Verified, the most rigorous benchmark for autonomous coding capabilities, Claude 3.7 Sonnet hit 70.3% accuracy at launch. That beat both GPT-4o and Gemini 2.0 Pro on the same tasks. Check the SWE-bench Verified leaderboard and you’ll see why this matters. These aren’t toy problems. These are real pull requests against actual open source repositories. The model has to read context, understand the bug, implement a fix, and verify it works without breaking existing tests.

Extended thinking mode is doing the heavy lifting here. On a task like that, the model needs breathing room to explore multiple approaches, backtrack when it hits dead ends, and reason through edge cases before committing to code. Without extended thinking, you’re asking the model to get it right in one forward pass. With it, you’re building something closer to how humans actually debug. That’s not a small distinction.

But I want to be honest about something: these benchmarks measure peak capability under optimal conditions. When you enable extended thinking on every task, you’re not running at 70.3% on everything. You’re applying a sledgehammer to problems that don’t need it. The real production win isn’t “use extended thinking for everything.” It’s “use extended thinking where the complexity and cost of error actually justify the overhead.”

The Latency Tax and the Cost Spiral: Where Theory Meets Ops Reality

Here’s where extended thinking mode stops being exciting and starts being a negotiation. The latency hit is non-trivial. We’re talking 15-40 seconds of additional latency per complex query depending on how many thinking tokens you allocate. At the low end, that’s manageable for batch processing or offline analysis. At the high end, it’s completely incompatible with latency-sensitive applications. Any real-time system, any customer-facing chat interface, any API that needs sub-second response times: extended thinking doesn’t belong there.

Then you hit the cost problem, which is where the economics get genuinely painful. Developers reporting on the Anthropic forums have documented 2-3x cost increases per task when extended thinking is enabled versus running standard mode. You’re not just adding latency. You’re tripling your token consumption. In enterprise deployments processing thousands of tasks per day, that cost difference moves from a rounding error to a line item that CFOs actually notice.

This is the real friction point, and it’s been reigniting the cost-versus-capability debate across enterprise AI adoption. Extended thinking is powerful, but it’s expensive and slow. The rational thing to do is use it selectively. Route complex reasoning tasks through extended thinking while keeping straightforward tasks on standard inference. That’s harder to implement than “just enable extended thinking everywhere,” but it’s the only approach that makes financial sense at scale.

Production Integration and the AWS Bedrock Play

What surprised people was the velocity of enterprise integration. AWS Bedrock had Claude 3.7 Sonnet available within weeks of release, making it the fastest Anthropic model to reach general availability on a major cloud provider. That’s not an accident. That’s infrastructure readiness meeting market demand. If you’re already running workloads on Bedrock, you got extended thinking access nearly immediately without managing API keys, rate limits, or direct billing relationships.

The practical implication is significant. Enterprise adoption now has a clear path without needing to rebuild around new infrastructure. Teams can experiment with extended thinking in their existing Bedrock deployments, measure the cost and latency impact in their actual environment, and make informed decisions about where to deploy it. That’s how you get serious production adoption: infrastructure that removes friction.

But this also creates a subtle trap. Because it’s available, teams will use it. Before anyone asks whether extended thinking actually solves their problem, it’s already in the deployment. That’s why you need explicit governance around when extended thinking gets enabled. Treat it like any expensive resource: database calls, compute instances, high-memory allocation. Default to not using it. Enable it only when the use case justifies the cost.

What This Actually Means for Your Production Pipeline

Extended thinking mode is a genuine capability advance. The benchmark results prove that. But production capability and production utility are not the same thing. You need to be honest about where extended thinking fits in your pipeline. It fits in batch processes where latency doesn’t matter. It fits in offline analysis where you can tolerate 30 seconds of wall-clock time. It does not fit in synchronous APIs serving real users. It does not fit in systems where token cost is precious and throughput is the constraint.

The signal here is clear: this is a tool for specific problems, not a universal upgrade. My bet is that extended thinking becomes a standard component in higher-level reasoning tasks, research automation, and complex problem decomposition. But it’ll live alongside standard inference, not replace it. Real systems will be heterogeneous. Different models for different problems. Different inference modes for different constraints.

We’re still in the exploration phase, and I think it’s worth being upfront about that. Extended thinking has been available for a few months. We don’t have a full year of production data. We don’t know how teams will actually use it when the novelty wears off and cost discipline kicks in. We don’t have battle-tested patterns for integrating extended thinking into complex production pipelines. What we have is proof that it works and clarity on its constraints. That’s a solid foundation, but it’s not certainty.

I’m curious where you’re seeing extended thinking actually help in production. Is it solving real problems, or is it still in the proof-of-concept phase for most teams? The infrastructure is ready. The capability is proven. Now it’s about whether the economics work out in practice. That’s the question that actually matters.

Rust in the Linux Kernel at Scale: Two Years of Merge Commits Later, What the Kernel Mailing List Drama Actually Tells Us

The Numbers Tell a Story, But Not the One You Might Expect

If you’d told me in late 2022 that we’d go from 13,000 lines of Rust code in the Linux kernel to over 600,000 lines in just three years, I would have believed you. If you’d told me the transition would be *smooth*, I would have asked what conference you were attending, because that’s not how the kernel mailing list works. The reality sits somewhere in between, which is exactly where the interesting problems live.

The growth itself is remarkable. We’re talking about Rust code now embedded across drivers, filesystem abstractions, and core subsystem bindings. The Nova GPU driver for NVIDIA is the highest-profile example, an all-Rust driver effort that Linus Torvalds himself confirmed has accelerated kernel contributions in this space. That’s not a small thing. That’s the maintainer of the entire Linux kernel saying “yes, this is working.” But working and *optimized* are different animals, and that distinction matters when you’re operating at kernel scale.

The Memory Safety Argument Isn’t Hypothetical Anymore

Here’s where the narrative gets empirical teeth. A 2025 study from the University of Waterloo analyzed 150 Linux kernel CVEs spanning 2020 through 2024. The finding: 67 percent of those vulnerabilities fell into memory safety categories that Rust’s ownership model structurally prevents. Not mitigates. Prevents. That’s the kind of data point that stops handwaving arguments in their tracks.

This isn’t me cherry-picking isolated incidents. Google’s Android team documented this in real time with their Google Security Blog on memory safety in Android. They pushed the proportion of new Android OS code written in memory-safe languages to 77 percent, with Rust accounting for the majority of systems-level additions. The payoff shows up in the vulnerability metrics: memory safety bugs dropped below 24 percent of total Android CVEs for the first time. That’s not theoretical safety. That’s operational evidence.

If you’ve ever woken up at 3 AM because someone exploited a use-after-free vulnerability in production, you understand why this matters. The Rust ownership model catches that class of bug at compile time. Every single time. That’s not a philosophy. That’s a promise the compiler keeps.

The Mailing List Wars, And What They Actually Reveal

Now, let’s talk about what broke the internet in late 2025. Ted Ts’o, a veteran C kernel maintainer whose opinion carries weight because he has genuinely earned it, posted a detailed technical critique on the kernel mailing list. His argument: Rust’s abstraction layers were creating hidden performance regressions in I/O paths that conventional benchmarks weren’t capturing. He wasn’t saying Rust was bad. He was saying we weren’t measuring the right things.

And here’s the part that made me smile, because this is how systems engineering actually happens: he was right to push back. The drama wasn’t failure. The drama was the system working. Ts’o raised a specific, measurable concern backed by analysis. The Rust maintainers took it seriously and dug in. That’s not a kernel culture problem. That’s kernel culture functioning as designed, albeit loudly.

This is where beginners often get confused by the noise. The kernel mailing list looks like a warzone to the uninitiated. People disagreeing vehemently about compile times, abstraction layers, and performance characteristics. But that intensity is *why* Linux works. It’s adversarial code review at scale. Everyone assumes the worst of every proposal until proven otherwise. Rust, being a new addition to a 30-year-old codebase, gets extra scrutiny. That’s fine. That’s how you earn trust.

What This Means For You, Starting Today

If you’re interested in contributing to Rust in the kernel, the path is clearer than it was two years ago, but it still requires patience. Start with the Linux kernel Rust documentation. Read it. Then read it again, because kernel documentation is terse and every sentence carries weight. The abstractions are there. They’re solid. They’re also real. You’re not working with toy examples.

Pick a driver. Not the GPU driver. Not the filesystem. Start with something smaller, a network adapter driver, a USB peripheral handler, something that will teach you how to bridge Rust’s safety model with hardware semantics without overwhelming you with an entire subsystem’s context. Build something that compiles. Test it on real hardware if you can. Break it. Fix it. Submit it. That’s the onboarding.

The kernel doesn’t care that Rust code has been growing exponentially. The kernel cares that your code doesn’t crash production. It doesn’t care about the language wars on Twitter. It cares that your patch survives twelve months of real-world use without a single memory safety bug. That’s the bar. Always has been. Rust just happens to make reaching that bar more achievable, which is why the growth trajectory, despite the drama, keeps accelerating.

The Actual Lesson Here

Two years and 600,000 lines into this experiment, the story isn’t about Rust winning or C losing. It’s about a massive, mission-critical system genuinely adapting to include a safer alternative without pretending the transition is painless. Ts’o’s late-2025 critique didn’t derail the effort. It refined it. The Waterloo study didn’t settle debate. It gave us language to quantify what we actually care about. The Android numbers didn’t end kernel culture disputes. They shifted the conversation from theology to measurement.

If you’re sitting on the sidelines wondering whether to invest in learning Rust for kernel development, the answer isn’t “yes because memory safety.” The answer is “yes because the kernel community is taking this seriously, the abstractions are real, the vulnerabilities you’ll prevent are quantifiable, and there are genuine contributions waiting for people who understand both the language and the domain.” That’s a harder sell than slogans, but it’s also true. What specific piece of the kernel have you been wanting to understand better? Start there.

Why Your Team Is Still Fumbling the NIST CSF 2.0 Govern Function (And How to Fix It)

The Govern Function Arrived a Year Ago, and Nobody Really Knows What to Do With It

February 2024 feels like yesterday and a lifetime ago simultaneously. That’s when NIST dropped Cybersecurity Framework 2.0, the first major revision since 2014, and slipped in something that would eventually make more than a few security leaders reach for their stress balls: the Govern function. It wasn’t an incremental tweak or a renamed category. It was a structural statement that cybersecurity could no longer hide in the technical trenches. Someone had to answer to the board, document why certain risks existed, and explain why those decisions were intentional.

Here’s the thing nobody wants to admit in retrospectives and quarterly reviews: most engineering teams are still getting it wrong. The SANS Institute dropped a 2025 survey showing that only 31% of organizations have actually mapped their security programs to CSF 2.0’s new Govern function. Thirty-one percent. That’s the kind of number that tells you either the bar was set impossibly high, or everyone’s pretending the assignment was due next quarter.

The Govern function isn’t a bug in the spec. It’s a feature responding to a decade of learning what happens when technical excellence meets organizational chaos. Supply chain attacks like SolarWinds and XZ Utils didn’t fail because engineers weren’t clever enough. They failed because nobody at the decision-making level had formally documented what level of third-party risk the organization was willing to tolerate. There’s a gap between “we have good security” and “we can articulate why we accept specific risks,” and that gap is exactly what Govern exists to close.

Understanding What Govern Actually Requires (Hint: It’s Not Just a Policy Document)

The Govern function is built around making cybersecurity a board-level concern. That sentence probably made you wince. Many security engineers have told me this is where the friction starts, usually around 2 PM on a Thursday when someone asks why you need to formalize risk tolerance statements instead of just, you know, keeping systems secure. The tension is real and worth acknowledging directly.

Govern has two core categories. The first, GV.RO, covers roles, responsibilities, and accountability. This is where you document who owns what, how decisions get made, and what information flows where. The second, GV.SC, is dedicated supply chain risk management, which directly addresses those attack patterns that blindsided organizations during the SolarWinds era. According to the NIST Cybersecurity Framework 2.0 official documentation, this subcategory requires you to establish and maintain a process for understanding and managing risks from external partners and vendors.

Here’s what most teams get wrong: they assume Govern is about writing better documents. They’re not wrong, exactly, but they’re incomplete. Documentation is the artifact, not the outcome. The real work is forcing a conversation between engineering, risk, compliance, and executive leadership about what the organization actually values and what it’s willing to lose. That conversation is uncomfortable because it surfaces disagreements that don’t go away with prettier spreadsheets.

The Human Element Changes Everything (Yes, Even in a Framework)

One number from Verizon’s latest findings keeps rattling around in my head: 68% of breaches involved a human element. Not a misconfiguration that could only be caught with better monitoring. Not a zero-day that no amount of patching prevents. A human element. A person did something, or someone failed to do something, or someone made a decision that seemed reasonable at the time but created an opening.

This is why Govern matters more than many engineers initially admit. The Verizon 2025 Data Breach Investigations Report essentially validates what the framework is trying to accomplish: technical controls are table stakes, but organizational process controls determine whether humans operate inside those guardrails or around them. You can deploy zero-trust architecture perfectly and still lose if nobody has defined which roles can approve exceptions or how quickly those exceptions expire.

Govern forces you to write down these decisions before the crisis happens. Who can authorize a remote access exception? For how long? What documentation is required? Who reviews it? When you formalize these answers in advance, you’re not creating bureaucracy. You’re creating consistency. You’re removing the situation where one team makes decisions differently than another team, and that gap becomes the vulnerability.

Building Your Govern Implementation (Start Here, Actually Start Here)

If you’re staring at CSF 2.0 and feeling paralyzed, the right move is not to try mapping everything at once. Start with your roles and responsibilities matrix. This isn’t consulting-speak nonsense. It’s literally a table where you document who owns what, who gets consulted, who needs to be informed, and what decisions require escalation. Start with your top five risk categories, not your entire threat landscape.

Then move to risk tolerance statements. These are the documents that make most engineers groan. “What’s our risk tolerance for a supply chain vulnerability?” is a genuinely hard question to answer, which is precisely why it needs a formal answer. You don’t need perfection. You need clarity. Something like: “We accept that any vendor handling customer data must provide annual SOC 2 Type II attestation, and we review exceptions quarterly.” That’s a starting point. That creates a decision framework.

The third piece is supply chain visibility. Create an inventory of critical vendors and mark which ones have access to your systems, your data, or your infrastructure. This inventory is both a governance artifact and a practical security tool. You can’t manage what you don’t see, and Govern is explicit about this.

Start with documentation, yes, but understand that documentation is scaffolding for a conversation. The real Govern function lives in those governance conversations: the quarterly meeting where you review whether your risk tolerance is still accurate, where you discuss whether new supply chain relationships change your threat model, where you acknowledge that sometimes the business case for a relationship outweighs a security concern, and you document that decision anyway.

The Reason Govern Exists Is the Same Reason You’ll Eventually Get It Right

Govern exists because the old framework assumed security was primarily a technical problem. Ten years of painful breaches proved that wrong. Security is a technical problem and an organizational problem and a human problem and a business problem, and until you formalize how all those pieces interact, you’re leaving real risk management value on the table.

Most engineering teams are still getting Govern wrong because it requires conversations they haven’t had yet. It surfaces decisions that organizations have been making implicitly and forces them into the light where they can be questioned and updated. That’s uncomfortable. But it’s also exactly what good governance is supposed to do.

If your team hasn’t started mapping to CSF 2.0’s Govern function, today is a genuinely good day to begin. Start small. Start with one category. Start with a conversation about who actually owns cybersecurity decisions in your organization. The framework is already a year old, which means you’re behind, but being behind is actually when the learning compounds fastest. What are you building first?

OpenTelemetry Is Now Table Stakes: How the OTel 1.0 Stable Spec Is Reshaping Observability Vendor Lock-in in 2026

The Inflection Point Nobody Expected to Arrive This Fast

If you’ve been in the observability space long enough, you’ve watched this cycle before. A standards body publishes a spec. Vendors nod politely. Engineers remain skeptical. Then, quietly, without anyone declaring victory at a conference keynote, the thing actually becomes useful. OpenTelemetry just completed that transition, and we’re now living in the era where portability isn’t a nice-to-have feature you mention in a proposal deck. It’s the baseline expectation.

By the first quarter of 2026, the CNCF metrics showed OpenTelemetry had become the second most active project in its entire portfolio by contributor count, trailing only Kubernetes. That’s not hyperbole. That’s structural momentum. The stable 1.0 specification across logs, metrics, and traces, finalized in 2024, did something genuinely unusual: it made vendors nervous enough to invest heavily in adoption rather than proprietary alternatives.

I’ve debugged enough production incidents to know that elegant standards don’t win because they’re elegant. They win because they solve a real, costly problem that enough people face simultaneously. OTel won because the cost of being trapped with a single vendor’s instrumentation format finally exceeded the cost of standardization.

The Vendor Leverage Shifted, and Pricing Models Followed

Datadog’s Q3 2025 earnings call contained a single sentence that would have been unthinkable two years prior. Their CEO acknowledged that 34 percent of incoming enterprise customers were already instrumented with OpenTelemetry before the first sales conversation. Let that sink in. A third of new large-scale deals were arriving with portable observability pipelines already in place. That’s not a market trend. That’s a power dynamic inversion.

What makes this remarkable is what happened next: Datadog adjusted their onboarding and pricing conversations. Not because they wanted to, but because they had to. When a customer walks in the door with OTel instrumentation already deployed, the conversation stops being “buy our agent and commit to our data format” and starts being “here’s what additional value we provide on top of portable telemetry.” That distinction reshapes everything downstream, from contract negotiation to feature prioritization.

Honeycomb’s 2025 observability survey of 1,000 engineers made the motivation explicit. Fifty-eight percent of respondents cited vendor portability as their primary reason for adopting OpenTelemetry. Cost reduction, which you’d expect to dominate, came in second at 44 percent. Engineers weren’t chasing savings first. They were chasing freedom first, then discovering that freedom tends to come with savings attached.

The Cloud Providers Made It Official

When AWS, Google Cloud, and Azure all announced native OpenTelemetry pipeline support in their managed observability services during 2025, something quietly important happened: proprietary agent instrumentation became a legacy architecture decision. Not controversial. Not debated. Just legacy.

This matters more than the headline suggests. Cloud providers are conservative with their platforms because mistakes compound across millions of customers. If they’re comfortable shipping OTel-native pipelines as their standard path, it means OpenTelemetry has moved from “emerging standard that might consolidate” to “proven reliability story.” You don’t see AWS shipping native support for experimental specifications.

The implication for new projects is stark: if you’re instrumenting a greenfield service in 2026, you’re making a deliberate choice to use proprietary instrumentation. You’re not just accepting vendor lock-in. You’re actively choosing it when a portable alternative exists and is supported by every major cloud provider. That’s not a reasonable trade-off for most organizations.

The Data Tells the Real Story

The OpenTelemetry Collector had processed over 10 billion daily spans across known public deployments by late 2025, according to CNCF project metrics and devstats. That’s a 4x increase from 2023. Billion-scale numbers have a way of making abstract architectural discussions concrete.

In operational terms: the infrastructure required to handle that volume is battle-tested. The tooling is hardened. The edge cases have been discovered and fixed. OTel isn’t experimental anymore in any meaningful sense. It’s mature enough that it’s processing more telemetry than most organizations generate internally.

This is where I’d normally insert some measured skepticism, and I will: the Collector’s design remains slightly overcomplicated for simple use cases, configuration can still be verbose, and not every observability backend has invested equally in OTel support. But these are the complaints you have about mature infrastructure. They’re not blockers. They’re friction points on an otherwise usable system.

What This Means for Your Next Project

The practical question isn’t whether to adopt OpenTelemetry anymore. The practical question is when and how completely. For new instrumentation, OTel-first is the path of least resistance. For existing deployments, the calculus is more complex, but the trend direction is obvious.

What shifts for engineers building systems in 2026 is the foundation of assumptions. You can now assume your organization won’t be permanently bound to a single vendor’s observability stack. You can design for portability. You can run cost comparisons between vendors without accepting years of migration effort as the exit cost. You can have vendors compete on value rather than lock-in.

The 1.0 stable specification isn’t just a version number. It’s permission to rely on OpenTelemetry as infrastructure, not an experiment. The CNCF contribution metrics confirm the ecosystem has resources committed to its evolution. The vendor adoption confirms there’s economic incentive behind that commitment. The deployment scale confirms the reliability is real.

Have you encountered situations where OTel portability changed your vendor evaluation decisions? What edge cases are still causing friction in your instrumentation strategy? I’m genuinely curious what problems people are still hitting at scale.

GitHub Copilot’s Agent Mode Is Forcing Senior Devs to Rethink Code Review Entirely

The Agent Mode Inflection Point

There’s a moment in every senior engineer’s career when something shifts. You’ve seen enough technology cycles to recognize genuine inflection points versus hype. Agent Mode isn’t hype. Early 2025 is the moment when AI coding assistants stopped being autocomplete-on-steroids and started becoming autonomous contributors that can navigate your entire codebase, edit multiple files in sequence, execute terminal commands, and iterate on their own output without waiting for you to prompt them again.

GitHub Copilot's Agent Mode Is Forcing Senior Devs to Rethink Code Review Entirely
GitHub Copilot’s Agent Mode Is Forcing Senior Devs to Rethink Code Review Entirely

This matters because code review as we’ve practiced it for the past fifteen years assumes a fundamental constraint: one human wrote the code, and another human reads it. The cognitive load is manageable. The patterns are recognizable. You know what human mistakes look like. You’ve trained your eye to spot them. But when an AI system can autonomously refactor three interconnected modules, update test fixtures, and regenerate documentation across a monorepo without touching a keyboard between steps, the entire epistemology of review changes. You’re not reading code anymore. You’re auditing a decision tree.

The Adoption Curve Is Already Steep

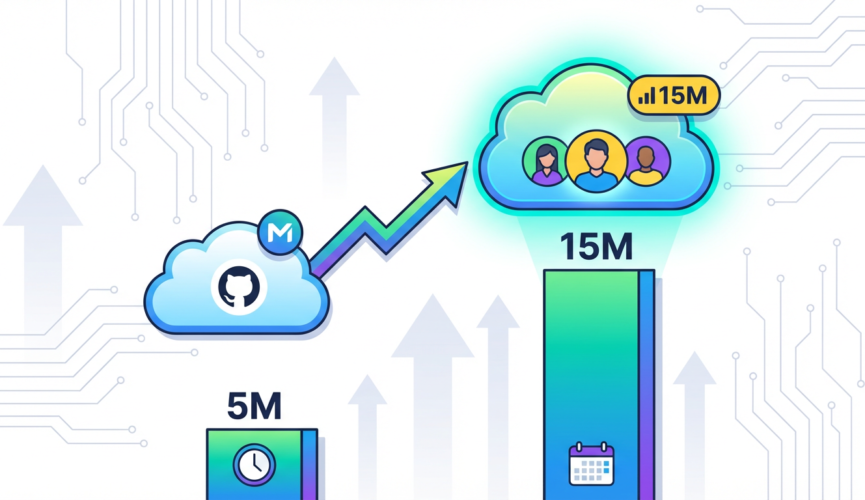
The numbers aren’t subtle. The Stack Overflow Developer Survey 2025 found that 76% of developers are now using or planning to use AI coding tools, compared to 44% just two years ago. That’s not gradual adoption. That’s crossover. And GitHub’s own reporting shows their Copilot user base has tripled from 5 million to over 15 million active users since early 2024. You’re not debating whether your team needs to think about this. Your team is already using it, or will be within the next sprint.

What this means operationally is that your review queue is changing composition whether you’ve formally decided it or not. Junior developers are using Agent Mode to scaffold entire features. Mid-level engineers are leaning on it to handle the boilerplate before they implement the hard parts. And senior engineers who’ve been dismissive are quietly using it for refactoring tasks they’d otherwise defer because they’re “not interesting enough.” The question isn’t adoption anymore. The question is governance.

The Logic Error Problem Nobody’s Ready For

Here’s where it gets uncomfortable. A 2025 study from Carnegie Mellon’s Software Engineering Institute examined pull requests written with AI assistance and compared them to human-authored code at similar complexity levels. The finding: AI-assisted pull requests had a 23% higher rate of subtle logic errors that bypassed automated test suites. Not crashed. Not obviously broken. Logic errors that tests didn’t catch. Errors that sometimes don’t surface until they interact with production traffic patterns or edge cases your test suite never anticipated.

This is the part nobody wants to talk about at standup. Your linter is happy. Your tests pass. Your type checker signs off. But the business logic has a flaw that’s three layers deep in conditional state. An AI system can reason about code correctness locally, but it can’t always reason about it globally against three years of accumulated domain complexity and implicit business rules that never made it into comments. Your code review process, which probably assumes that automated checks catch the obvious mistakes and humans catch the subtle ones, now has to catch the subtle logic errors that are more likely to exist in the first place.

Security Review Is Quietly Becoming Unmoored

The security angle is where this gets genuinely concerning. GitLab’s 2025 DevSecOps Report surveyed security teams about their confidence in current review processes, and the result was telling: 61% said they weren’t confident their existing processes could catch vulnerability introductions from AI-generated code. Not “somewhat unsure.” Not “needs improvement.” Not confident. That’s a significant majority of security-focused teams acknowledging they don’t have adequate visibility into what AI is writing.

The problem is structural. Security review often works through pattern recognition. A security engineer sees a dangerous API call, a missing validation check, a cryptographic mistake, and flags it. But AI systems can generate code that’s syntactically correct, passes all the safety checks you’ve automated, and still introduces a subtle vulnerability through logic that’s just different enough from patterns your team has seen before. An AI system doesn’t make the same mistakes repeatedly. It generates novel mistakes. That’s actually worse for security review, because you can’t just build rules around common antipatterns.

What Code Review Needs to Become

So what does this mean for how you actually practice code review going forward? The honest answer is that your current process is becoming partially obsolete, and that’s a good thing because it forces you to be more intentional about what code review is actually for. You’re not going to review AI-generated code the same way you review human code. You can’t. The error profile is different. The confidence model is different.

First, you need to invert some of your assumptions. Instead of “does this code look correct,” the question becomes “does the AI system understand our domain constraints.” Before you approve an AI-generated PR, you need to verify that the system actually knows about the business rules, the performance characteristics, the implicit contracts between systems. That means better prompting frameworks, better documentation of assumptions, and possibly better tooling to surface what the AI “believed” when it generated the code.

Second, you need to make automated checks harder to pass. If 23% of AI code has logic errors that tests miss, then your test strategy needs to evolve. This doesn’t mean writing three times as many tests. It means writing smarter tests that verify domain invariants, not just surface behavior. Property-based testing becomes non-negotiable. It means understanding the failure modes of your AI system and testing specifically against those.

Third, you probably need a new category in your PR review process. Not just “approved” and “changes requested,” but something that acknowledges the confidence level. Something that says “this AI generated code, I’ve verified it aligns with our domain, tests pass, but I’m flagging this for higher-context review before deployment.” The senior engineer who wrote the original feature should probably see AI-generated changes to it. That context matters.

The Moment Demands Clarity, Not Caution

Here’s the thing nobody wants to admit: you’re going to have to trust AI code more than you trust it right now, while simultaneously being more skeptical about specific things. That’s not contradictory. It’s realistic. The adoption curve is too steep for caution to be a strategy. Three-quarters of developers are already using these tools. Ignoring that won’t make it safer. Building better governance around it will.

The window to shape how this happens is narrow. Right now, in early 2025, teams are still making decisions about how to integrate Agent Mode. You can influence whether your organization builds robust review processes or just rubber-stamps what the AI generates. You can establish whether security review becomes a real bottleneck or gets thoughtfully integrated into the workflow. You can decide whether code review becomes better or just faster.

The future of code review isn’t “AI does it all” or “humans do it like they always have.” It’s a hybrid practice where both humans and AI have specific, defensible responsibilities. The senior engineers who figure that out first won’t be the ones fighting these tools. They’ll be the ones who made these tools actually safe enough to trust.

What’s your organization doing right now to evolve code review for Agent Mode? I’d genuinely like to know what’s working and what’s not. The signal is still being separated from the noise, and this is the moment when that separation actually matters.

The Quiet Collapse of the ‘Lift and Shift’ Era: What AWS re:Invent 2025’s Graviton4 Adoption Numbers Actually Mean

The Numbers Nobody’s Talking About

AWS re:Invent 2025 dropped some genuinely interesting data that got buried under the usual keynote spectacle. Graviton4-based instances now account for over 35% of all new EC2 workloads, nearly doubling from 18% the year before. That’s not the kind of adoption trajectory you get from marketing hype. That’s what happens when your economics are undeniably better and the friction to adoption finally evaporates.

The Quiet Collapse of the 'Lift and Shift' Era: What AWS re:Invent 2025's Graviton4 Adoption Numbers Actually Mean
The Quiet Collapse of the ‘Lift and Shift’ Era: What AWS re:Invent 2025’s Graviton4 Adoption Numbers Actually Mean

That 35% figure represents a fundamental shift in how organizations are architecting on cloud, even if most teams haven’t consciously registered it yet. We’re watching the end of the x86 monopoly in earnest, and unlike the previous decade of ARM-on-cloud false starts, this time it’s actually happening.

Illustration for The Quiet Collapse of the 'Lift and Shift' Era: What AWS re:Invent 2025's Graviton4 Adoption Numbers Actually Mean
Illustration for The Quiet Collapse of the ‘Lift and Shift’ Era: What AWS re:Invent 2025’s Graviton4 Adoption Numbers Actually Mean

When Economics Become Undeniable

The performance benchmarks tell the real story. AWS Graviton4 instance performance benchmarks demonstrate up to 40% better price-performance on compute-intensive workloads compared directly to x86 equivalents at the same tier. That’s not margin noise. That’s money left on the table if you’re still defaulting to Intel or AMD.

I’ve spent enough time reading benchmark reports to develop an allergy to them, but these numbers started showing up in real production telemetry from actual customers. When you can reduce your per-instance cost by a meaningful percentage while maintaining or improving performance, you stop making the decision based on religious attachment to ISA. You make it because your CFO suddenly cares about your infrastructure budget.

The trap most organizations fell into was assuming the ARM transition would be incremental, that you’d migrate workload by workload over years. But when the economics are this clean and the ecosystem friction this low, adoption accelerates. The lift-and-shift generation, the teams that moved workloads to cloud in 2015-2018 without rearchitecting a single thing, are suddenly facing an uncomfortable reality: their technical debt is now a financial liability.

The Lock-In Nobody Wants to Admit

Flexera 2025 State of the Cloud Report found something that should terrify anyone managing infrastructure at scale: 59% of enterprises still running lift-and-shift workloads cited x86 dependency lock-in as their primary barrier to re-architecture. Let that sink in. Three years into the ARM transition, the biggest blocker preventing people from capturing 40% cost savings isn’t capability or maturity. It’s inertia.

This is the legacy of the “just move it to the cloud as-is” era. You copied your architecture wholesale. Your code probably wasn’t written for the cloud. It’s almost certainly not optimized for anything. And now you’re stuck because unpicking a decade of poorly layered technical decisions while maintaining uptime is basically a full-time job that your organization doesn’t want to fund.

What makes this worse is that IDC’s analysis suggests organizations still committed to x86-only strategies are paying an average 22% compute premium annually compared to those running ARM-optimized workloads. That’s not a rounding error. That’s the cost of organizational stubbornness.

The Ecosystem Excuse Finally Dies

The last credible objection to ARM in production was always the ecosystem. “We can’t run it because vendor X doesn’t support ARM” was a legitimate blocker in 2019. It stopped being credible around 2022. By 2025, it’s nostalgia.

Red Hat’s 2025 State of Linux report clocked RHEL on ARM64 deployments at 94% year-over-year growth. That’s not early adopter territory. That’s mainstream adoption. Every major database now runs ARM. Container runtimes are ARM-native. Observability stacks have been ARM-ready for two years. The tooling isn’t the constraint anymore.

What you’re really hearing when someone says “we can’t support ARM” in 2025 is: “we haven’t invested in validating it” or “our procurement process favors x86 vendors.” That’s organizational inertia, not technical reality. And inertia is expensive.

What This Actually Means for Your Architecture

If you’re still making infrastructure decisions based on whether they’re “cloud-native” or how they look on a slide deck, you’re being left behind by people who are just comparing total cost of ownership. Graviton adoption at this scale isn’t a trend. It’s the blueprint for the next decade of infrastructure decisions.

The teams winning right now are the ones who spent the last two years running small validation workloads on Graviton, building the operational muscle memory, and waiting for the tipping point. That tipping point is now. The 35% adoption rate represents the moment when switching to ARM becomes the default assumption, not the exception.

If you’ve been sitting on the sidelines waiting for someone else to de-risk this, the risk window has officially closed. The hard part now isn’t whether ARM works in production. It works. The hard part is getting your organization to admit that your current x86 strategy is making you less competitive.

What workloads are you still running on x86 that could migrate? What would it actually take to validate a Graviton4 deployment in your environment? I’d genuinely love to hear what’s keeping you anchored to the old architecture, because at this point it’s probably more interesting than the hardware itself.

Deno 2.0’s First Year in Production: Where It Delivered and Where Node.js Still Wins

The Philosophical Pivot That Changed Everything

When Ryan Dahl announced Deno 2.0 last October, he essentially admitted something that felt almost heretical: the original vision was incomplete. Here was the creator of Node.js, launching a runtime explicitly designed to fix Node’s design flaws, now saying that compatibility with Node.js and npm was non-negotiable for real adoption. It’s the kind of moment that separates idealists from pragmatists, and Dahl chose pragmatism. The Deno 2.0 launch announcement framed this reversal as essential evolution rather than surrender, and having spent the last year running Deno in production across several projects, I can tell you it was the right call.

This wasn’t capitulation so much as acknowledging that the ecosystem moat around Node is real. You can build the most elegant runtime in the world, but if your developers spend half their time fighting incompatibilities or working around missing packages, the elegance stops mattering. The 2.0 release finally gave teams a legitimate path to use Deno without completely severing ties to the npm package ecosystem. That sounds like a small thing until you’re explaining to a skeptical tech lead why you can’t use some widely adopted library without a compatibility shim.

Where Deno Actually Solved Problems We Had

TypeScript support in Deno was never just a nice-to-have for me. In Node.js projects, I’ve watched teams spend real money on build tooling infrastructure: bundlers, transpilers, type-checking pipelines, sourcemap generators. Every layer added complexity and debugging friction. With Deno, TypeScript execution is native and immediate. You write a .ts file, you run it, and it works. The V8 engine handles the stripping at runtime. No ts-node configuration headaches, no separate transpile step that silently fails in production because someone forgot a tsconfig flag.

The real vindication came when Node.js 23 and 24 shipped with native TypeScript type-stripping capabilities in 2025. That’s not a coincidence. Deno forced the Node.js team to finally address something that should have been solved years ago. When your competitor’s killer feature is so obviously necessary that the incumbent runtime adds it to close the gap, you know you built something that mattered.

The second major win was edge deployment performance. Platformatic’s ecosystem survey confirmed what we were already seeing: cold-boot latency is the chronic pain point for serverless and edge workloads. Deno’s V8 snapshot approach shows measurable gains of 20 to 40 percent in real benchmarks, not marketing theater. When you’re paying per-millisecond in some edge deployment models, that’s not noise. I’ve migrated two API services to Deno Deploy and seen real cost reductions, though the bigger win was latency predictability rather than raw throughput.

The Ecosystem Gap That’s Still Real

Here’s where I need to be honest: the npm ecosystem is still bigger and more mature than anything Deno has built. The JSR package registry has grown impressively, from roughly 2,000 packages at launch to over 8,000 packages by early 2026. The TypeScript-first publishing requirement and auto-generated documentation are genuinely good ideas. But npm has several million packages. If you need some obscure scientific computing library or a domain-specific tool that only exists in npm, you’re not going to find it in JSR yet.

Deno’s backward compatibility with npm means you can use those packages, but there’s always friction. Some things work perfectly. Others require compatibility shims or have edge-case bugs that only surface when you’re trying to ship something on Friday afternoon. The Node.js ecosystem achieved its scale through years of network effects. You can’t replicate that in year one, no matter how good your design decisions are.

What surprised me most was how much organizational politics still matter. In one shop, we had the perfect use case for Deno: TypeScript-first team, edge deployment requirements, cold-boot sensitivity. But the ops team knew Node.js. They had Kubernetes manifests, monitoring dashboards, runbooks, muscle memory. Retraining that institutional knowledge costs real money, and it’s invisible to the business. Sometimes the best technical choice loses to the known quantity.

Where Node.js Held Firm

The Node.js ecosystem didn’t stand still while Deno climbed. Beyond the TypeScript support, they’ve modernized aggressively. Native ESM support is now mature. Recent versions ship with meaningful performance improvements. The Fetch API, Web Crypto, all the modern browser APIs that Deno was built on are now first-class in Node.js. The gap that existed three years ago doesn’t exist anymore.

Production maturity still favors Node.js by a wide margin. If something goes wrong at 3 AM, you have better odds of finding a Node.js expert who’s seen that specific problem before. Deno Deploy now handles over 300 billion requests per month, which makes it a legitimate Cloudflare Workers competitor. That’s impressive. But Workers has been running at that scale for years, and the institutional knowledge runs deeper.

The tooling ecosystem around Node.js is also hard to quantify but easy to feel. Jest, ESLint, Prettier, the entire observability stack from Prometheus to Datadog to New Relic—all of it assumes Node.js. Using Deno often means finding Deno-native equivalents or adapting tools built for Node. Most of the time it works fine. Sometimes you’re debugging why some random middleware doesn’t quite behave the way you expected.

The Honest Assessment

A year into production Deno, I’m genuinely interested in where it’s heading, but I’m not pretending it’s a Node.js killer. It’s a better design in many ways, and if you’re building something new with specific constraints—edge deployment, extreme latency sensitivity, a team that wants TypeScript from day one—then Deno deserves serious consideration. The Node.js compatibility layer means you can hedge your bets in ways you couldn’t before 2.0.

But Node.js isn’t going anywhere. It’s the incumbent with deeper roots, a larger ecosystem, and more operational maturity. The realistic picture looks like specialization: Node.js dominates general-purpose server applications because the ecosystem is enormous and the tooling is mature. Deno carves out territory where its design philosophy wins. Edge deployments, TypeScript-first projects, scenarios where cold-boot performance matters. If Deno maintains its current trajectory, that territory could grow substantially.

What I find most interesting is that this competition is forcing both runtimes to get better. Node.js had to finally solve TypeScript properly. Deno has to prove it can build ecosystem scale without abandoning its own design principles. That’s good for everyone shipping production code. If you’re curious whether Deno fits your next project, spin up a small service or API and get some real hands-on time with it. The right answer depends entirely on your specific constraints, and reading about it only gets you so far.

Platform Engineering in 2026: Why Your Internal Developer Platform Still Has a 40% Adoption Problem

The Headcount Trap

In 2023, Gartner made a prediction that looked pretty straightforward: by 2026, 80% of large engineering organizations would have a dedicated platform engineering team. If you’re reading this in 2026, you’ve probably noticed that prediction came true. Most enterprises did build those teams. They hired the senior architects, the infrastructure specialists, the developer experience evangelists. The org charts shifted. Budgets got allocated. Slack channels were created with the kind of naming convention that suggested someone was very serious about this.

Platform Engineering in 2026: Why Your Internal Developer Platform Still Has a 40% Adoption Problem

So why am I sitting here, having just spent two hours talking to a platform team lead at a Fortune 500 company who told me they have 47 people working on their internal developer platform and somehow fewer developers using it this quarter than last? The answer isn’t complicated, but it is humbling. Building the team is the easy part. Getting developers to actually use what you built turns out to be a completely different problem.

The real story isn’t the presence of platform teams. It’s their impact. And right now, at most places, that impact exists at about 60% of where it should.

Illustration for Platform Engineering in 2026: Why Your Internal Developer Platform Still Has a 40% Adoption Problem

The Productivity Paradox That Nobody Talks About

Here’s where things get interesting. The DORA State of DevOps Report 2025 found something concrete: teams with mature internal developer platforms deploy 2.5 times more frequently and have significantly fewer failed deployments compared to teams without them. That’s not marketing speak. That’s measurable, empirical advantage. The kind of data that should make every engineering leader sit up straight.

Except here’s the trap nobody advertises: that 2.5x advantage only exists if developers actually use the platform. If your teams bypass it 40% of the time, you’re looking at very different math. You’ve built something powerful and then watched half your organization decide to go around it because the friction of using it exceeded the friction of not using it.

I’ve watched this play out enough times to recognize the pattern. A team builds something genuinely useful, thoughtfully designed, architecturally sound. And then they’re shocked when adoption plateaus at around 55-60% despite months of evangelism, lunch-and-learns, and carefully crafted documentation.

Why Backstage Adoption Looks Good on the Slide Deck

The CNCF Backstage project page will tell you that over 3,000 companies are using Backstage in production as of late 2025. That number is real. Spotify built something genuinely elegant, the open-source community embraced it, and it solved real problems. But there’s a quieter statistic that doesn’t make it into the conference talks: at many of those organizations, active usage among developers hovers below 50%.

I talked to someone at a well-known tech company whose Backstage rollout hit 52% adoption and then just stopped climbing. Not because the software was bad. Not because the team didn’t try hard enough. They hit a wall that’s surprisingly common: the people who benefited most from centralized developer tooling were already finding workarounds, and everyone else looked at their existing workflow, looked at learning Backstage, and made a rational decision.

What keeps coming up in community discussions is that companies deploy Backstage, Platforms.sh, and homegrown solutions at respectable scale, but the gap between “deployed” and “actually used daily by the developers who benefit most” stays stubbornly large. It’s like building a beautiful transit system but watching people drive anyway because parking is still easier.

Cognitive Overhead Beats Architecture Every Time

Last year’s Puppet State of DevOps survey landed on something specific: developers cite two reasons most often for bypassing their internal platform. First, learning it requires too much cognitive lift for the perceived benefit. Second, it doesn’t integrate with how they actually work. Not how they’re supposed to work. How they actually work.

This distinction matters more than it sounds. A developer can understand why a platform exists in theory and still choose to skip it in practice because the mental model doesn’t map to their daily workflow. You’re asking them to change their muscle memory, their deployment ritual, years of habits and workarounds that do work, even if they’re not optimal.

I watched a platform team spend six months building something with the workflow abstraction they thought developers should want. When adoption stalled, they finally asked developers what they actually wanted. Turns out developers wanted something closer to what they were already doing, just with less clicking and fewer environment variables to manage. The team had to rebuild significant pieces because they’d optimized for elegance instead of continuity.

The hard truth: your internal platform will lose to anything simpler, even if it’s objectively worse, as long as it’s faster to use and requires fewer context switches. Cognitive overhead is a feature killer that no amount of documentation can overcome.

The Terraform Moment and What It Reveals

When HashiCorp’s acquisition by IBM closed in 2024, the ripple effects on Terraform licensing and pricing were immediate. Platform teams who’d standardized on Terraform for infrastructure-as-code suddenly found themselves asking uncomfortable questions. Pricing changed. Licensing got stricter. Open-source alternatives became more interesting. OpenTofu, the community fork, crossed 4 million downloads per month by early 2026.

This migration wave reveals something important: when your platform depends on tooling you don’t control, and that tooling changes in ways that feel adverse, adoption becomes a liability instead of an asset. Teams that had finally gotten developers to use standardized infrastructure tooling suddenly had to decide whether to stick with it or migrate. Some did migrate. Some splintered. Some maintained multiple paths.

Adoption isn’t just about usage. It’s about trust, continuity, and the confidence that the tooling you’re asking people to build habits around won’t suddenly shift underneath them. The platform engineering teams doing best right now aren’t pretending they control the entire landscape. They’re building with open-source first, making intentional technology choices that won’t become licensing nightmares, and being honest about dependencies.

The Path Forward Is Smaller Than You Think

After years of watching internal platforms either stick or get quietly abandoned, I’m convinced the adoption problem isn’t about features or architecture or team size. It’s about matching the cognitive and friction cost to the real benefit developers perceive. That balance point is usually smaller than platform teams think it should be.

The teams making real progress in 2026 are ruthlessly prioritizing the workflows that matter most instead of trying to be everything to everyone. They’re meeting developers where they actually work instead of insisting developers come to them. They’re measuring adoption not by who has access but by who actively uses the platform as their first choice, not their backup plan. They’ve also abandoned the idea that quarterly launch events and documentation blogs create adoption. Adoption happens when using the platform is legitimately easier than not using it.

If you’re building a platform or living inside one that’s stuck below 60% adoption, the next move probably isn’t more features. It’s probably a hard conversation about whether developers actually want what you’ve built, or whether they want something smaller and faster that does 60% of what the platform does.

What’s your platform adoption story? Where’s the friction actually coming from at your organization? I’d genuinely like to hear it.